
INTRODUCTION
In stock market data projects, reference data often looks simple. It may only contain stock symbols, company names, sectors, listing boards, broker codes, or broker names. But in practice, this type of data becomes the foundation for almost every larger market analysis workflow.
Before building a stock dashboard, broker activity analysis, trading screener, or market monitoring system, we need clean and consistent reference data.
This notebook solves that problem by combining two APIs: getIdxSymbols and getBrokerCodes.
The getIdxSymbols API is used to retrieve IDX stock symbols, while getBrokerCodes is used to retrieve broker code data. After retrieving both datasets, the notebook cleans and standardizes the data, then creates a summary output that can be used as a reference layer for future stock analysis projects.
This tutorial walks through each cell in the notebook exactly according to the existing code structure.
Cell 1 — Import Library + Config API
import os
import json
import time
from typing import Any, Dict, List, Optional, Union

import requests
import pandas as pd

RAPIDAPI_HOST = "indonesia-stock-exchange-idx.p.rapidapi.com"
BASE_URL = f"https://{RAPIDAPI_HOST}"

# Ganti dengan RapidAPI Key Anda
RAPIDAPI_KEY = "ISI_RAPIDAPI_KEY_ANDA_DI_SINI"

# Alternatif jika memakai environment variable:
# RAPIDAPI_KEY = os.getenv("RAPIDAPI_KEY")

if not RAPIDAPI_KEY or RAPIDAPI_KEY == "ISI_RAPIDAPI_KEY_ANDA_DI_SINI":
    raise ValueError("Masukkan RapidAPI Key Anda dulu pada variabel RAPIDAPI_KEY.")

HEADERS = {
    "Content-Type": "application/json",
    "x-rapidapi-host": RAPIDAPI_HOST,
    "x-rapidapi-key": RAPIDAPI_KEY,
}

print("API configuration ready.")
Explanation
Cell 1 prepares the required libraries and API configuration.
The notebook imports several libraries such as os, json, time, requests, and pandas. The requests library is used to call the API endpoints, while pandas is used to process the response data into dataframes.
The typing module, including Any, Dict, List, Optional, and Union, is used for type annotations in the helper functions. This makes the function structure easier to read and maintain.
The notebook then defines:
RAPIDAPI_HOST
and
BASE_URL
These variables are used to build the API endpoint URLs.
The RAPIDAPI_KEY variable stores the RapidAPI key. In a public tutorial, the real API key should never be exposed. That is why the article uses a placeholder:
ISI_RAPIDAPI_KEY_ANDA_DI_SINI
The notebook also provides an alternative way to load the API key from an environment variable:
# RAPIDAPI_KEY = os.getenv("RAPIDAPI_KEY")This is a safer option for production or shared notebooks.
The validation section checks whether the API key is empty or still using the placeholder value. If it is, the notebook raises a ValueError.
Finally, the HEADERS dictionary is created. It contains the required request headers: Content-Type, x-rapidapi-host, and x-rapidapi-key.
Cell 2 — Helper Function
def request_get(
    endpoint: str,
    params: Optional[Dict[str, Any]] = None,
    timeout: int = 30
) -> Union[Dict[str, Any], List[Any]]:
    url = f"{BASE_URL}{endpoint}"

    time.sleep(0.2)

    response = requests.get(
        url,
        headers=HEADERS,
        params=params,
        timeout=timeout
    )

    try:
        payload = response.json()
    except Exception:
        payload = response.text

    if not response.ok:
        raise RuntimeError(
            f"Request gagal. Status: {response.status_code}\n"
            f"URL: {response.url}\n"
            f"Response: {payload}"
        )

    return payload


def find_first_list(obj: Any) -> List[Dict[str, Any]]:
    if isinstance(obj, list):
        return obj if all(isinstance(item, dict) for item in obj) else []

    if isinstance(obj, dict):
        priority_keys = [
            "data", "result", "results", "items", "rows",
            "content", "symbols", "brokers", "brokerCodes"
        ]

        for key in priority_keys:
            if key in obj:
                found = find_first_list(obj[key])
                if found:
                    return found

        for value in obj.values():
            found = find_first_list(value)
            if found:
                return found

    return []


def json_to_dataframe(payload: Union[Dict[str, Any], List[Any]]) -> pd.DataFrame:
    records = find_first_list(payload)

    if records:
        return pd.json_normalize(records)

    if isinstance(payload, dict):
        return pd.json_normalize(payload)

    return pd.DataFrame()


def detect_column(df: pd.DataFrame, keywords: List[str]) -> Optional[str]:
    if df.empty:
        return None

    lower_map = {col.lower(): col for col in df.columns}

    for keyword in keywords:
        if keyword.lower() in lower_map:
            return lower_map[keyword.lower()]

    for col in df.columns:
        col_lower = col.lower()
        if any(keyword.lower() in col_lower for keyword in keywords):
            return col

    return None


def safe_series(df: pd.DataFrame, col: Optional[str], default_value="") -> pd.Series:
    if col is None or col not in df.columns:
        return pd.Series([default_value] * len(df), index=df.index)

    return df[col]
Explanation
Cell 2 contains helper functions that make the notebook more flexible and easier to maintain.
The first function is request_get. This function sends a GET request to an API endpoint. The endpoint is combined with BASE_URL, then sent using requests.get.
Inside this function, time.sleep(0.2) adds a short delay before making the request. This helps prevent the notebook from sending requests too aggressively.
After receiving the response, the function tries to parse it as JSON. If that fails, it stores the response as plain text.
If the API request fails, the function raises a RuntimeError containing the status code, request URL, and response payload. This makes debugging easier when the API does not return the expected result.
The second function is find_first_list. This function searches through a JSON object and returns the first list of dictionaries it can find. This is useful because API responses may have different structures. Sometimes the data is inside data, sometimes inside result, items, symbols, brokers, or brokerCodes.
The third function is json_to_dataframe. This function converts the API payload into a pandas dataframe. It first uses find_first_list to locate a list of records. If records are found, the function normalizes them using pd.json_normalize. If not, it normalizes the dictionary directly.
The fourth function is detect_column. This function detects a column based on a list of possible keywords. It first checks for exact lowercase matches, then checks whether any keyword appears inside the column name.
The final function is safe_series. This function safely returns a dataframe column. If the requested column is not found, it returns a default series with the same length as the dataframe.
Together, these helper functions make the notebook more robust against variations in API response structures.
Cell 3 — Retrieve Data from getIdxSymbols and getBrokerCodes APIs
idx_symbols_payload = request_get(
    endpoint="/api/main/symbols",
    params={"range": 100}
)

broker_codes_payload = request_get(
    endpoint="/api/main/broker-codes"
)

idx_symbols_df = json_to_dataframe(idx_symbols_payload)
broker_codes_df = json_to_dataframe(broker_codes_payload)

idx_symbols_df["source_api"] = "getIdxSymbols"
broker_codes_df["source_api"] = "getBrokerCodes"

print("IDX Symbols shape:", idx_symbols_df.shape)
print("Broker Codes shape:", broker_codes_df.shape)

display(idx_symbols_df.head())
display(broker_codes_df.head())

print("Preview IDX Symbols JSON:")
print(json.dumps(idx_symbols_payload, indent=2, ensure_ascii=False)[:1500])

print("\nPreview Broker Codes JSON:")
print(json.dumps(broker_codes_payload, indent=2, ensure_ascii=False)[:1500])
Explanation
Cell 3 retrieves data from the two main APIs.
The first request calls the endpoint:
/api/main/symbols
with the parameter:
range: 100
This endpoint represents getIdxSymbols, which retrieves IDX stock symbol data.
The second request calls:
/api/main/broker-codes
This endpoint represents getBrokerCodes, which retrieves broker code data.
The raw API responses are stored in:
idx_symbols_payload
and
broker_codes_payload
After that, both payloads are converted into dataframes using the json_to_dataframe function.
The resulting dataframes are:
idx_symbols_df
and
broker_codes_df
The notebook then adds a source_api column to both dataframes. For stock symbols, the value is getIdxSymbols. For broker codes, the value is getBrokerCodes.
This makes it clear where each dataset comes from.
The notebook prints the shape of both dataframes and displays the first few rows. It also prints a preview of the raw JSON response from both APIs using json.dumps, limited to the first 1500 characters.
This cell is the main data retrieval step. At this point, the notebook has successfully collected raw IDX stock symbols and broker code data.
Cell 4 — Cleaning and Data Standardization
# Deteksi kolom IDX Symbols
symbol_col = detect_column(
    idx_symbols_df,
    ["symbol", "ticker", "stockCode", "stock_code", "code", "securityCode"]
)

company_name_col = detect_column(
    idx_symbols_df,
    ["name", "companyName", "company_name", "stockName", "stock_name", "issuer"]
)

sector_col = detect_column(
    idx_symbols_df,
    ["sector", "sectorName", "sector_name", "industry"]
)

board_col = detect_column(
    idx_symbols_df,
    ["board", "marketBoard", "market_board", "listingBoard"]
)


# Deteksi kolom Broker Codes
broker_code_col = detect_column(
    broker_codes_df,
    ["brokerCode", "broker_code", "code", "id", "kode"]
)

broker_name_col = detect_column(
    broker_codes_df,
    ["brokerName", "broker_name", "name", "companyName", "company_name"]
)


print("Detected IDX Symbols columns:")
print("symbol       :", symbol_col)
print("company name :", company_name_col)
print("sector       :", sector_col)
print("board        :", board_col)

print("\nDetected Broker Codes columns:")
print("broker code  :", broker_code_col)
print("broker name  :", broker_name_col)


idx_symbols_clean = pd.DataFrame({
    "symbol": (
        safe_series(idx_symbols_df, symbol_col, "")
        .astype(str)
        .str.upper()
        .str.strip()
    ),
    "company_name": safe_series(idx_symbols_df, company_name_col, ""),
    "sector": safe_series(idx_symbols_df, sector_col, ""),
    "board": safe_series(idx_symbols_df, board_col, ""),
})

idx_symbols_clean = idx_symbols_clean[idx_symbols_clean["symbol"].ne("")].copy()
idx_symbols_clean["source_api"] = "getIdxSymbols"


broker_codes_clean = pd.DataFrame({
    "broker_code": (
        safe_series(broker_codes_df, broker_code_col, "")
        .astype(str)
        .str.upper()
        .str.strip()
    ),
    "broker_name": safe_series(broker_codes_df, broker_name_col, ""),
})

broker_codes_clean = broker_codes_clean[broker_codes_clean["broker_code"].ne("")].copy()
broker_codes_clean["source_api"] = "getBrokerCodes"


display(idx_symbols_clean.head(20))
display(broker_codes_clean.head(20))
Explanation
Cell 4 cleans and standardizes both datasets.
The first section detects important columns from idx_symbols_df.
The notebook tries to find the stock symbol column using possible names such as:
symbol, ticker, stockCode, stock_code, code, and securityCode.
Then it tries to find the company name column using possible names such as:
name, companyName, company_name, stockName, stock_name, and issuer.
It also detects sector and listing board columns using keywords such as:
sector, sectorName, sector_name, industry, board, marketBoard, market_board, and listingBoard.
The second section performs a similar process for broker code data.
The broker code column is detected using possible names such as:
brokerCode, broker_code, code, id, and kode.
The broker name column is detected using possible names such as:
brokerName, broker_name, name, companyName, and company_name.
After the column detection process, the notebook prints the detected column names so users can verify whether the right columns were found.
Next, the notebook creates idx_symbols_clean. This dataframe standardizes stock symbol data into four main columns:
symbol
company_name
sector
board
The symbol column is converted into uppercase and stripped of extra spaces. Rows with empty symbols are removed. The notebook also adds:
source_api = "getIdxSymbols"
Then, the notebook creates broker_codes_clean. This dataframe standardizes broker data into:
broker_code
broker_name
The broker_code column is also converted into uppercase and stripped of extra spaces. Rows with empty broker codes are removed. The notebook adds:
source_api = "getBrokerCodes"
At the end, the notebook displays the first 20 rows of both cleaned dataframes.
This cell transforms raw API responses into cleaner and more consistent reference datasets.
Cell 5 — Combine into a Project Output
summary_df = pd.DataFrame({
    "dataset": [
        "IDX Symbols",
        "Broker Codes"
    ],
    "source_api": [
        "getIdxSymbols",
        "getBrokerCodes"
    ],
    "total_rows": [
        len(idx_symbols_clean),
        len(broker_codes_clean)
    ],
    "total_columns": [
        idx_symbols_clean.shape[1],
        broker_codes_clean.shape[1]
    ]
})


project_metadata = pd.DataFrame({
    "project_name": ["IDX Symbols and Broker Codes Reference Project"],
    "description": [
        "Project ini menggabungkan master data kode saham IDX dan kode broker menjadi satu referensi data."
    ],
    "idx_symbols_rows": [len(idx_symbols_clean)],
    "broker_codes_rows": [len(broker_codes_clean)],
    "symbols_range_parameter": [100]
})


display(summary_df)
display(project_metadata)
Explanation
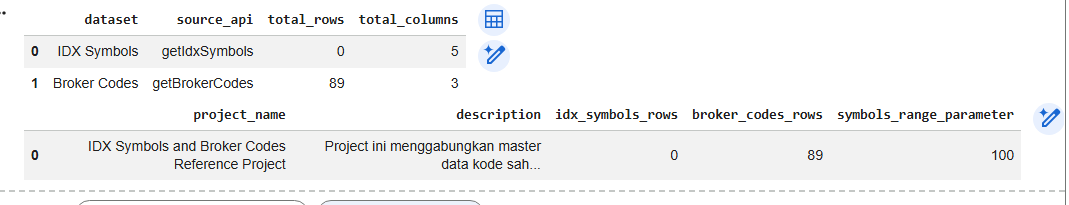
Cell 5 creates the final project output.
First, the notebook creates a dataframe called summary_df.
This dataframe summarizes the two datasets:
IDX Symbols
and
Broker Codes
For each dataset, it records:
source_api
total_rows
total_columns
This gives users a quick overview of the cleaned stock symbol and broker code datasets.
Then, the notebook creates another dataframe called project_metadata.
This dataframe stores general project information, including:
project_name
description
idx_symbols_rows
broker_codes_rows
symbols_range_parameter
The description explains that the project combines IDX stock symbol master data and broker code master data into one reference dataset.
The symbols_range_parameter value is 100, which comes from the parameter used when calling the getIdxSymbols endpoint.
Finally, the notebook displays both summary_df and project_metadata.
This cell closes the workflow by creating a readable project summary and metadata output.
Result:
Overall Project Workflow
This notebook follows a simple but important data workflow.
First, it prepares the API configuration and RapidAPI credentials.
Second, it defines helper functions for making API requests, detecting JSON structures, converting API responses into dataframes, detecting columns, and safely handling missing columns.
Third, it retrieves data from two APIs:
getIdxSymbols
and
getBrokerCodes
Fourth, it cleans and standardizes the stock symbol and broker code datasets.
Fifth, it creates summary and metadata outputs.
The final result is not a trading signal or price analysis. Instead, it is a clean reference dataset that can support more advanced stock market projects.
Why This Case Matters
Many stock data projects immediately focus on prices, volume, technical indicators, or buy-and-sell signals. But before building those layers, we need reliable reference data.
A stock symbol must be consistent. A company name must be readable. Broker codes must be standardized. Data sources must be clear. Without this foundation, larger stock market systems become harder to maintain.
By combining getIdxSymbols and getBrokerCodes, this notebook creates a reference layer for IDX stock market data.
This is not just about calling two APIs. It is about building the foundation for future stock analysis workflows.
Conclusion
This notebook shows how to build IDX stock reference data using Python and two APIs: getIdxSymbols and getBrokerCodes.
getIdxSymbols retrieves IDX stock symbol data, while getBrokerCodes retrieves broker code data. Both datasets are converted into dataframes, cleaned, standardized, and summarized into a project output.
The most valuable part of this workflow is its focus on data foundation. Before building dashboards, broker activity analysis, stock screeners, or market monitoring systems, we need clean reference data.
With this workflow, users can create a simple master reference dataset containing IDX stock symbols and broker codes. This dataset can later support more advanced projects such as broker activity analysis, IDX stock dashboards, stock screeners, and market monitoring tools.
In the end, the project is not only about using APIs. It is about preparing a clean and reliable data layer before moving into deeper stock market analysis.